Vigil: a fast child-safety risk classifier
Our research model that reads a conversation and scores seven risk categories plus severity in a single pass. Small, fast and built for on-device use.
Vigil is still being tested
01
Research preview
Vigil is a research model. It is not in the SafeCircle app yet and has only been tested on synthetic chats. Horizon is the model that protects your family today.
Honest status
Vigil is a research preview. It has not been run on a phone yet, all of its training data is synthetic, and on text from unfamiliar generators it still flags 12–21% of harmless chats. Friendly teasing between friends is its weakest area. Horizon is the model that runs in the SafeCircle app today.
What Vigil does
01
Seven risk categories
Grooming, bullying, sexual content, isolation, requests for personal information, moving the chat to another platform, and threats.
02
Severity and confidence
Each answer comes with a severity from none to critical and a calibrated confidence, with thresholds tuned on a false-alarm budget.
03
Fast and typed
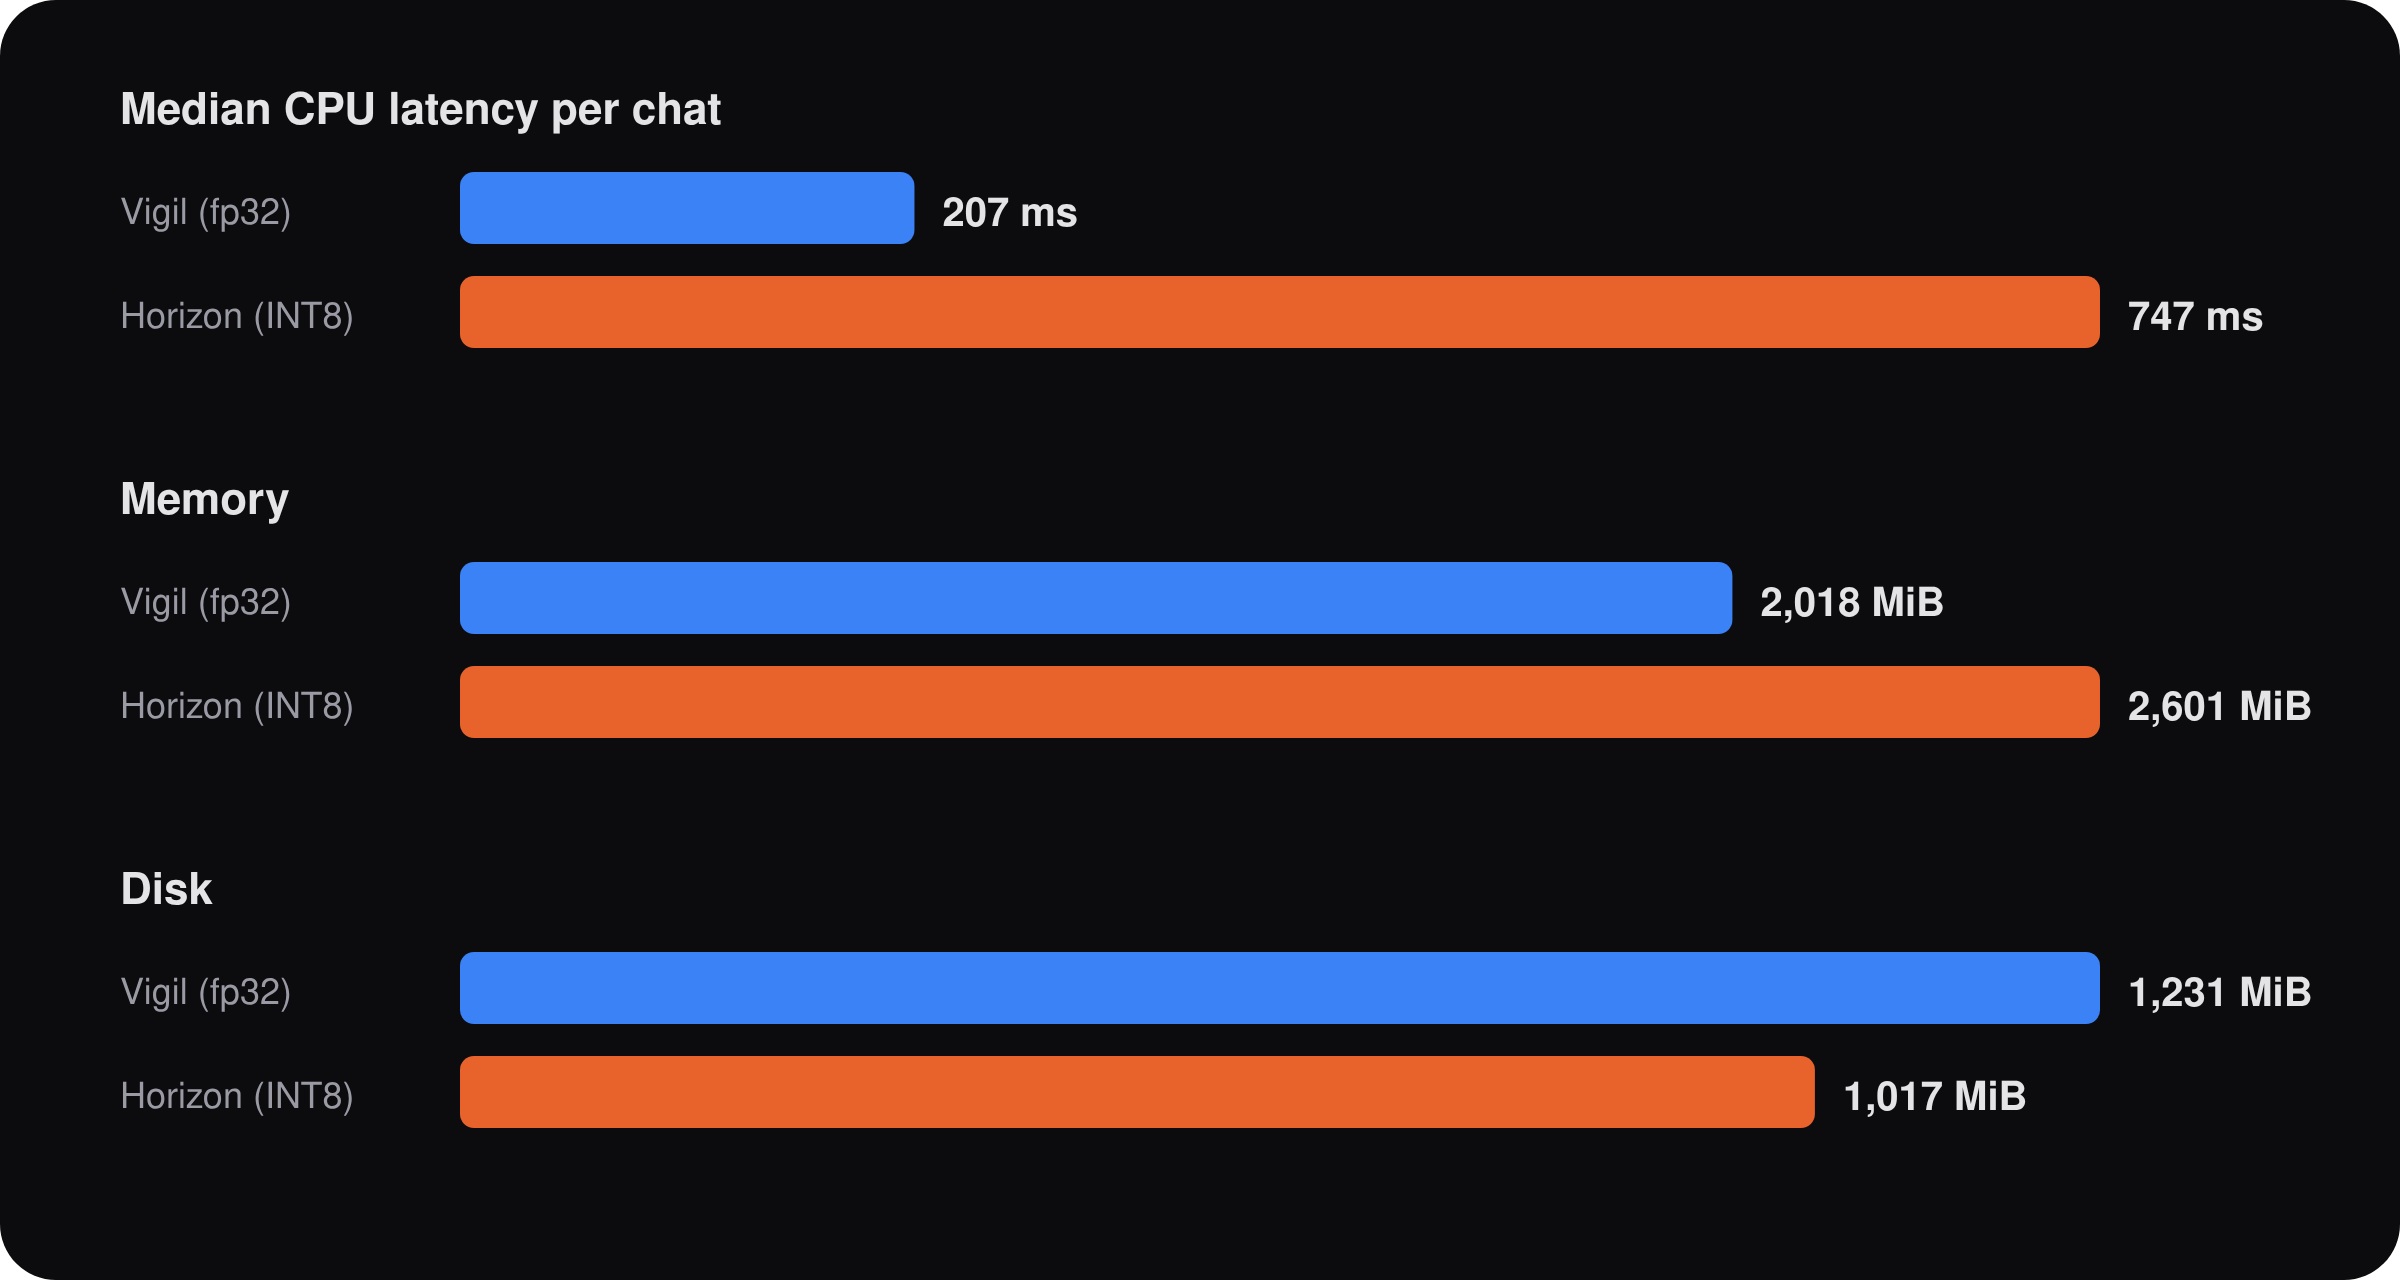
One encoder pass instead of generated text: about 11 ms per conversation on a GPU and about 207 ms on an 8-CPU node.
04
On-device ready
Exports to ONNX and LiteRT so it can run inside the SafeCircle Android app. It is not shipped yet.
Catches more, on text it has never seen
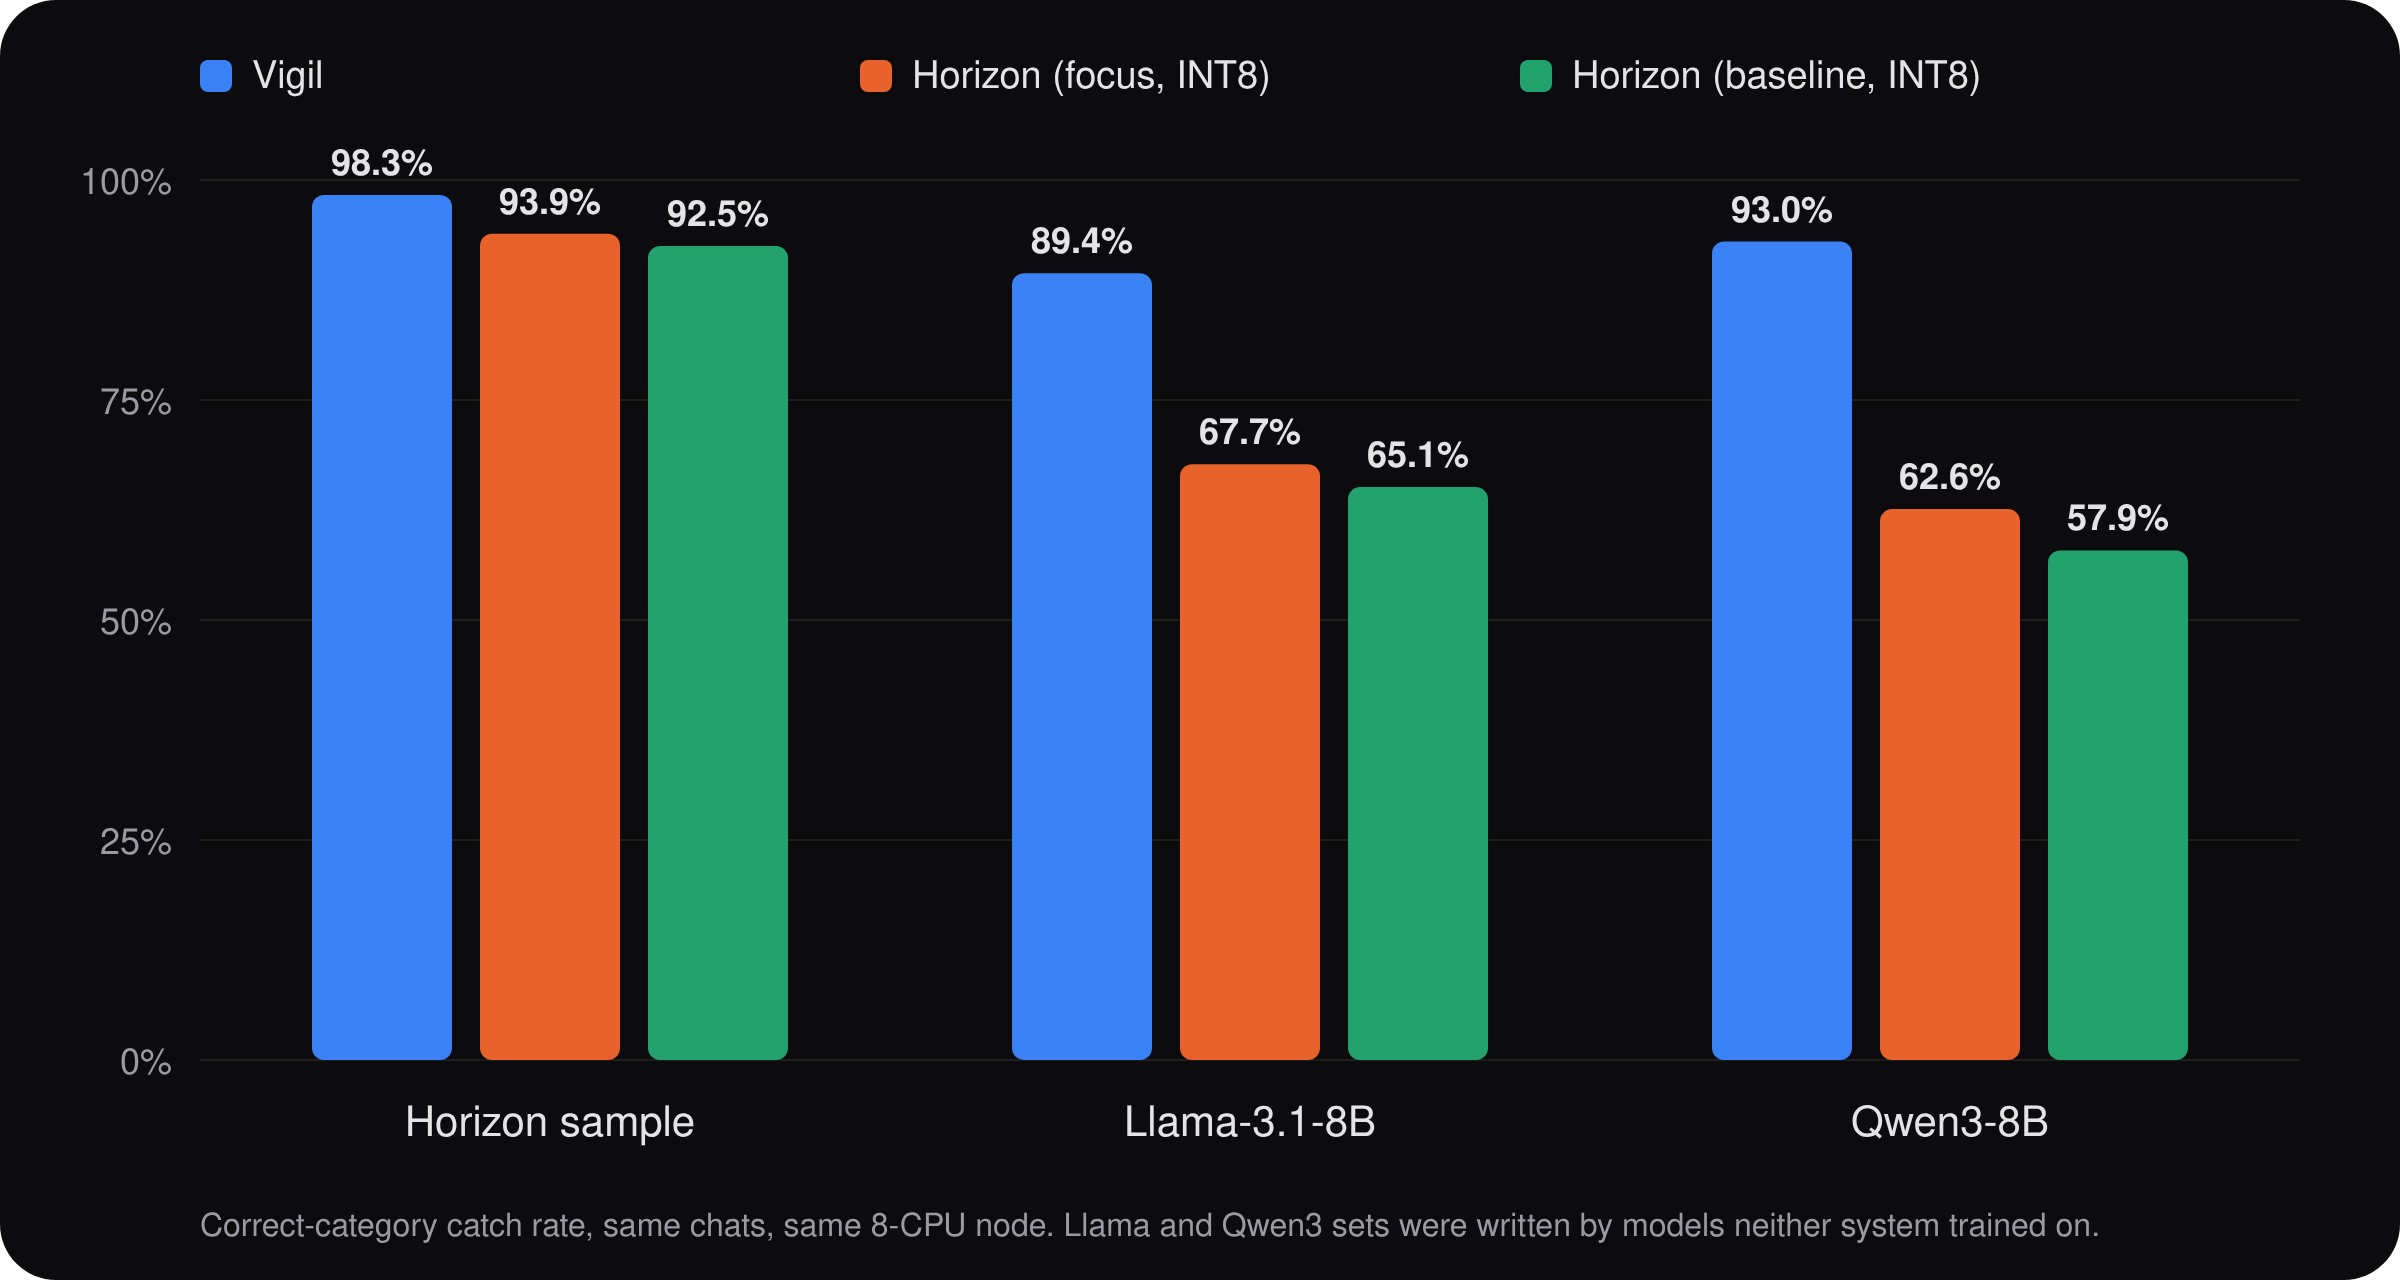
Across three chat sets Vigil finds the right risk category in 89-98% of risky conversations, against 63-94% for Horizon. The two harder sets were written by other models that neither system trained on.
3.6x faster on a CPU
One encoder pass instead of generated text: a median 207 ms against 747 ms on the same 8-CPU node, with less memory. The model file is larger on disk (1,231 vs 1,017 MiB) because Vigil is fp32.
Vigil vs Horizon
| Measure | Vigil | Horizon (INT8) |
|---|---|---|
| Approach | Encoder classifier, one pass | Generative model (Gemma 3 1B / Llama 3.2 3B) |
| Median CPU latency per chat | 207 ms | 747 ms |
| Memory | 2,018 MiB | 2,601 MiB |
| Disk | 1,231 MiB | 1,017 MiB |
| Shipped on-device | Not yet | Yes (LiteRT-LM) |
Open and reproducible
Vigil is a full fine-tune of Laya-multilingual (English and Spanish tested). The model, training pipeline and results log are public: see the model on Hugging Face and the code on GitHub.